In 2017, Dario Amodei wrote a short internal memo making an unfashionable bet: the path to smarter AI isn't a stream of clever inventions. It's a simple, general recipe, scaled up until it's enormous.
Imagine two chefs trying to make the world's best soup. The first spends years inventing secret techniques: a special knife cut, a precise stirring rhythm, a sauce only she understands. The second does something that sounds almost lazy. She gets a bigger pot, more and better ingredients, and lets it simmer longer.
For most of AI's history, researchers acted like the first chef. Dario's memo argued that the second chef wins, and that she keeps winning as the pot gets bigger. He called the idea "the Big Blob of Compute": a blob, because the model is a big shapeless mass of adjustable numbers, and compute, because what feeds it is raw calculating power.
He wrote it before ChatGPT, before GPT-3, before almost anyone outside a few labs had heard of a large language model. In a February 2026 interview with Dwarkesh Patel, he said he still holds the same hypothesis and hasn't seen much that contradicts it.
Say you want a computer to recognize dogs. The old way is to write down what a dog is: four legs, fur, barks. The blob way is to show a big, general-purpose learner millions of photos labeled "dog" or "not dog" and let it work out the pattern on its own.
Pick an animal. See how a hand-written rule copes, versus a learner trained on millions of photos.
Every fix to the rulebook ("dogs can have three legs… unless it's a cat") makes it longer and more fragile. The learner doesn't need fixes. It needs more examples and a bigger brain to absorb them. That's the trade the Big Blob makes: give up on hand-crafting, and spend on scale instead.
Two years after Dario's memo, the computer scientist Rich Sutton published a short essay called "The Bitter Lesson" that reached the same conclusion from 70 years of AI history. In chess, Go, speech recognition and computer vision, researchers built systems around human knowledge. Those systems won early. Then simpler methods that could soak up more computing power overtook them, and the clever versions were abandoned.
It's "bitter" because it stings: the cleverness researchers were proudest of turned out to be a short-term advantage.
The rulebook approach starts strong and stalls. The general learner starts weak and keeps climbing.
The memo's core claim is that only a handful of things really matter. Dario has said he listed seven. Here they are, in kitchen terms.
How many calculations you can afford. Today that means warehouses of specialized chips running for months.
The amount of text, images and examples the model gets to learn from. A big pot with three carrots makes thin soup.
A cookbook that only has soups won't teach you desserts. The data has to be good, and it has to cover the range of things you want the model to do.
How long the model keeps practicing on that data. Pull it off the heat too early and the flavors never come together.
A task you can keep getting better at forever. "Guess the next word" is the famous one: there's always another sentence to practice on. Newer models also learn from rewards for good answers, the way you'd train with practice problems.
Technical tricks that stop the giant calculation from boiling over or going cold, so, in Dario's word, it flows "laminar": smooth instead of turbulent.
Notice what's missing from the list: there's no ingredient called "a brilliant new idea about how thinking works." Ideas still matter, but mostly as ways to let the blob get bigger without falling apart. The next companion piece, on the 2017 paper "Attention Is All You Need", is a perfect example: its big contribution was a design that let computers learn from far more data, far faster.
The ingredients have to grow together. Picture a barrel made of wooden planks: it can only hold water up to its shortest plank. Pour in a mountain of computing power with too little data, and most of it is wasted.
This isn't hypothetical. In 2022, researchers at DeepMind showed that many of the largest models of the time had been fed too little data for their size. A smaller model trained on more text, which they called Chinchilla, beat much bigger rivals for the same budget.
Move the sliders. The blob only grows when the ingredients grow together.
Here's the part that turned the hypothesis into a business. In 2020, a group of researchers at OpenAI, Dario among them, measured how a language model's mistakes shrink as you scale it up. The result was startlingly regular: each time you multiply the compute by ten, the error drops by about the same proportion. They called these patterns scaling laws.
Think of a staircase where every step costs ten times more than the last, but the steps are reliably the same height. Expensive, yes. But predictable, and predictability is what lets a company justify spending a billion dollars before it knows exactly what it will get.
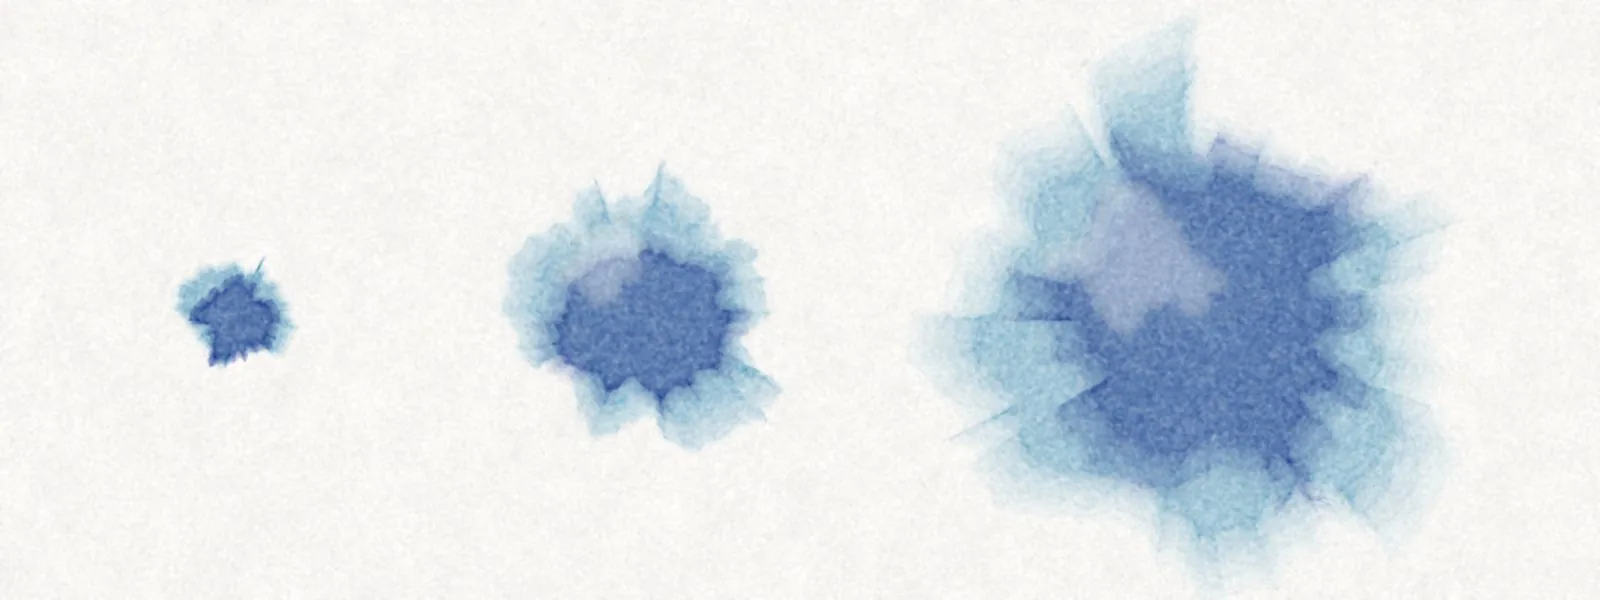
Each click multiplies the compute by 10. Watch the error fall by the same fraction each time, and the bill grow.
The last two items on Dario's list sound the most technical, but the idea is familiar. Inside a model, numbers get passed through hundreds of layers, multiplied again and again. If each layer makes them just a little bigger, they explode. A little smaller, and they fade to nothing. It's the screech of a microphone held too close to a speaker: a tiny signal, fed back on itself, becomes a roar.
Normalization is the fix. After each layer, the numbers get gently re-centered, the way a thermostat keeps a room at the same temperature. Boring, essential, and the reason the blob can grow huge without collapsing.
Each layer nudges the numbers 40% bigger. Watch what happens with and without re-centering.
It's a hypothesis, and smart people push back on it. Here is the strongest version of each side.